Held-out runs with the cause named2026-10-13, nine variants across six fault families, three fresh seeds each, with the engine, manifests and acceptance criteria frozen before the run.
Same held-out set, 27 runs0
False RESOLVED diagnosesZero false strong authority, zero false elimination and the decoy never named. An execution witness was recorded in 24/27 runs.
WATCH lab, 2026-09-30 / 10-01~1.2 s
Median change-to-journal latency105 changes in the WATCH + follow comparison; p90 1.9 s, down from a 21.5 s polling median.
Every published measurement0 model calls
Measured deterministic evaluation pathsTestbed, live suite and ITBench-Lite all ran on the deterministic policy. An LLM can only choose among legal reads; the causal judgment stays in code.
A payment dependency fault can surface as an order-service error. A Deployment rollout, a failing Pod and a NetworkChaos experiment can all sit near that symptom in the graph. Their temporal overlap and structural proximity do not establish which actor initiated it.
The hard cases are incomplete: an execution witness arrives late, a recreated Pod reuses a name, a trace backend loses reads, or two independent faults affect different symptom groups. The testbed even exposed a rule that granted strong authority to an experiment that had ended 40 minutes before onset.
The system therefore separates evidence acquisition from judgment. It asks whether a cause actually executed, whether its effect reached the affected instance and whether a competing explanation remains. Stale evidence and missing observations must limit an answer. Persisting that reasoning makes it reviewable and reproducible.
The independently deployable Connector stays inside the customer Kubernetes cluster with its Kubernetes and telemetry credentials. It dials out over gRPC with mutual TLS; the remote control plane holds no customer Kubernetes credentials. Read-only RBAC and an application deny list exclude Secrets from observation.
In remote mode a Connector runs inside the customer cluster, holds every credential with read-only RBAC and no Secrets, lists and watches each scope, and dials out to the control plane over gRPC with mutual TLS; nothing is exposed inbound. Inside the control plane, the alert stream opens or continues incidents and the change stream feeds an evidence journal that records object versions, observation times and explicit gaps. Each diagnosis revision freezes its evidence manifest. The deterministic RCA engine forms hypotheses and information gaps, a bounded investigator spends one legal read at a time through the Connector with every read taped, and each observation becomes a typed Finding before verification and resolution run again. The stored revision carries its coverage record and digests, and remediation is proposed for an operator, never executed.
01
Connector boundary
The Connector is the only component that touches the cluster; it dials out, and the control plane holds no customer credential.
Kubernetes API and Alertmanager and Prometheus, Loki, Tempo reads Connector. Connector mTLS Gateway.
ObservabilityKubernetes APIobjects + Events, list + watch
OutputConsole, API, reportssingle, competing, not established
BoundaryProposed remediationoperator reviews, never executed
03
Deterministic RCA loop
The engine forms hypotheses, the bounded investigator spends one legal read, and evidence is normalized into a Finding before the diagnosis can change.
Alert + observation cutoff seeds Deterministic RCA. Deterministic RCA requests one read Bounded investigator. Bounded investigator executes One legal observation. One legal observation stores EvidenceStore → normalization. EvidenceStore → normalization rebuild + verify Leader by claim tier (causal path, confidence, resolution). EvidenceStore → normalization rebuild + verify Remaining gap (loops back for one more read).
ClientAlert + observation cutoffchanges and symptoms at the boundary
seeds
ControlDeterministic RCAhypotheses, information gaps
ServiceOne legal observationthrough the Connector, within budget
stores
ControlEvidenceStore → normalizationtyped Finding
rebuild + verify
OutputLeader by claim tiercausal path, confidence, resolution
BoundaryRemaining gaploops back for one more read
Architecture notes
The investigator and the judge are separate: an optional LLM policy can choose among already-legal reads, but normalization, hypothesis rebuilding, verification and root-cause resolution stay deterministic, and every reported measurement ran with zero model calls.
In remote mode the control plane holds no customer credential. Secrets are denied twice, by read-only RBAC and by the Connector's deny list; preflight, one-time enrollment, certificate rotation, revocation and Helm packaging are implemented and lab-validated.
The Connector watches each scope instead of polling: on the lab a change reached the journal at a median of 1.2 s, down from 21.5 s, and a watch that cannot resume gaps only its own scope.
Evidence is admitted by when the Connector observed it. Each revision records per-scope source continuity and transport completeness; configuration frontier closure requires continuous observation and proven delivery.
Each revision freezes its evidence manifest and the ordered tape of provider reads, so offline replay can verify the manifest, tape and epistemic digests. Remediation is proposed for an operator and never executed.
Kubernetes API + Events
Object versions, ownership, lifecycle and changes through per-scope LIST + WATCH. Unresumable watches produce explicit gaps.
Alertmanager + Prometheus
Alerts open incident episodes; bounded metric reads supply symptom and resource-pressure context.
Loki + Tempo
Bounded logs and attributed traces supply observations of execution, service effects and propagation.
PostgreSQL + console
The control plane journals evidence and freezes diagnosis inputs. The React/TypeScript console renders persisted judgments and recorded causal edges.
WATCH ingestion measured about 1.2 s median / 1.9 s p90 change-to-journal latency in the lab, versus 21.5 s / 27.1 s with 15-second polling (2026-09-30 / 10-01).
Connector preflight, one-time enrollment, certificate rotation, revocation and Helm packaging are implemented and validated in the lab, and the console walks an operator through connecting a cluster.
Alertmanager context arrives through the Connector. Intake records the alert occurrence, incident episode and observation cutoff.
2
Observations and changes are captured
LIST + WATCH feeds object versions, Events, lifecycle records and explicit scope gaps into the PostgreSQL evidence journal.
3
Findings become causal hypotheses
Deterministic normalization attaches typed Findings to resource instances. Directional topology supplies candidate claim paths, rather than treating graph proximity as causality.
4
Investigation fills evidence gaps
The bounded investigator selects one legal read through the Connector, within turn, read, wall-time and per-gap budgets. The ordered provider-read tape records what actually ran.
5
Rules verify causal claims
The engine rebuilds hypotheses and checks execution, effect, symptom coverage, material rivals and open frontier questions. The investigator never decides the root cause; an optional LLM can only select already-legal reads.
6
A diagnosis revision is persisted
The result freezes its evidence manifest, provenance and per-scope coverage. Offline replay verifies the manifest, read tape and epistemic digest against the retained evidence.
7
The operator inspects the explanation
The console connects the causal path to Findings, raw observations, timeline and revision history. Competing explanations remain visible; remediation is proposed for human review and never executed.
RESOLVED
Evidence establishes the causal mechanism, covers declared symptoms and disambiguates material alternatives. It describes a diagnosis, not a remediated cluster.
AMBIGUOUS
A supported explanation exists, but rivals, open frontier questions or uncovered symptoms prevent a conclusive attribution.
INSUFFICIENT_EVIDENCE
Available observations cannot support an adequate causal explanation. Budget exhaustion and NO_DATA cannot manufacture certainty.
Confidence (VERIFIED / LIKELY / UNVERIFIED) and resolution answer different questions. A correct leading actor can still be AMBIGUOUS. The investigator gathers evidence; deterministic rules own all three resolution outcomes.
The Causal X-Ray keeps the recorded causal path beside the Investigation, Evidence, Timeline and Diagnosis views. Selecting a resource, Finding or causal node highlights its context and scopes related evidence. The frontend draws persisted engine edges; disconnected graph components remain disconnected.
Recorded on a copy of a held-out lab run: packet loss on payment-service. The engine identifies the NetworkChaos experiment as a supported possible cause and keeps the diagnosis AMBIGUOUS. This is testbed evidence, not a customer incident.
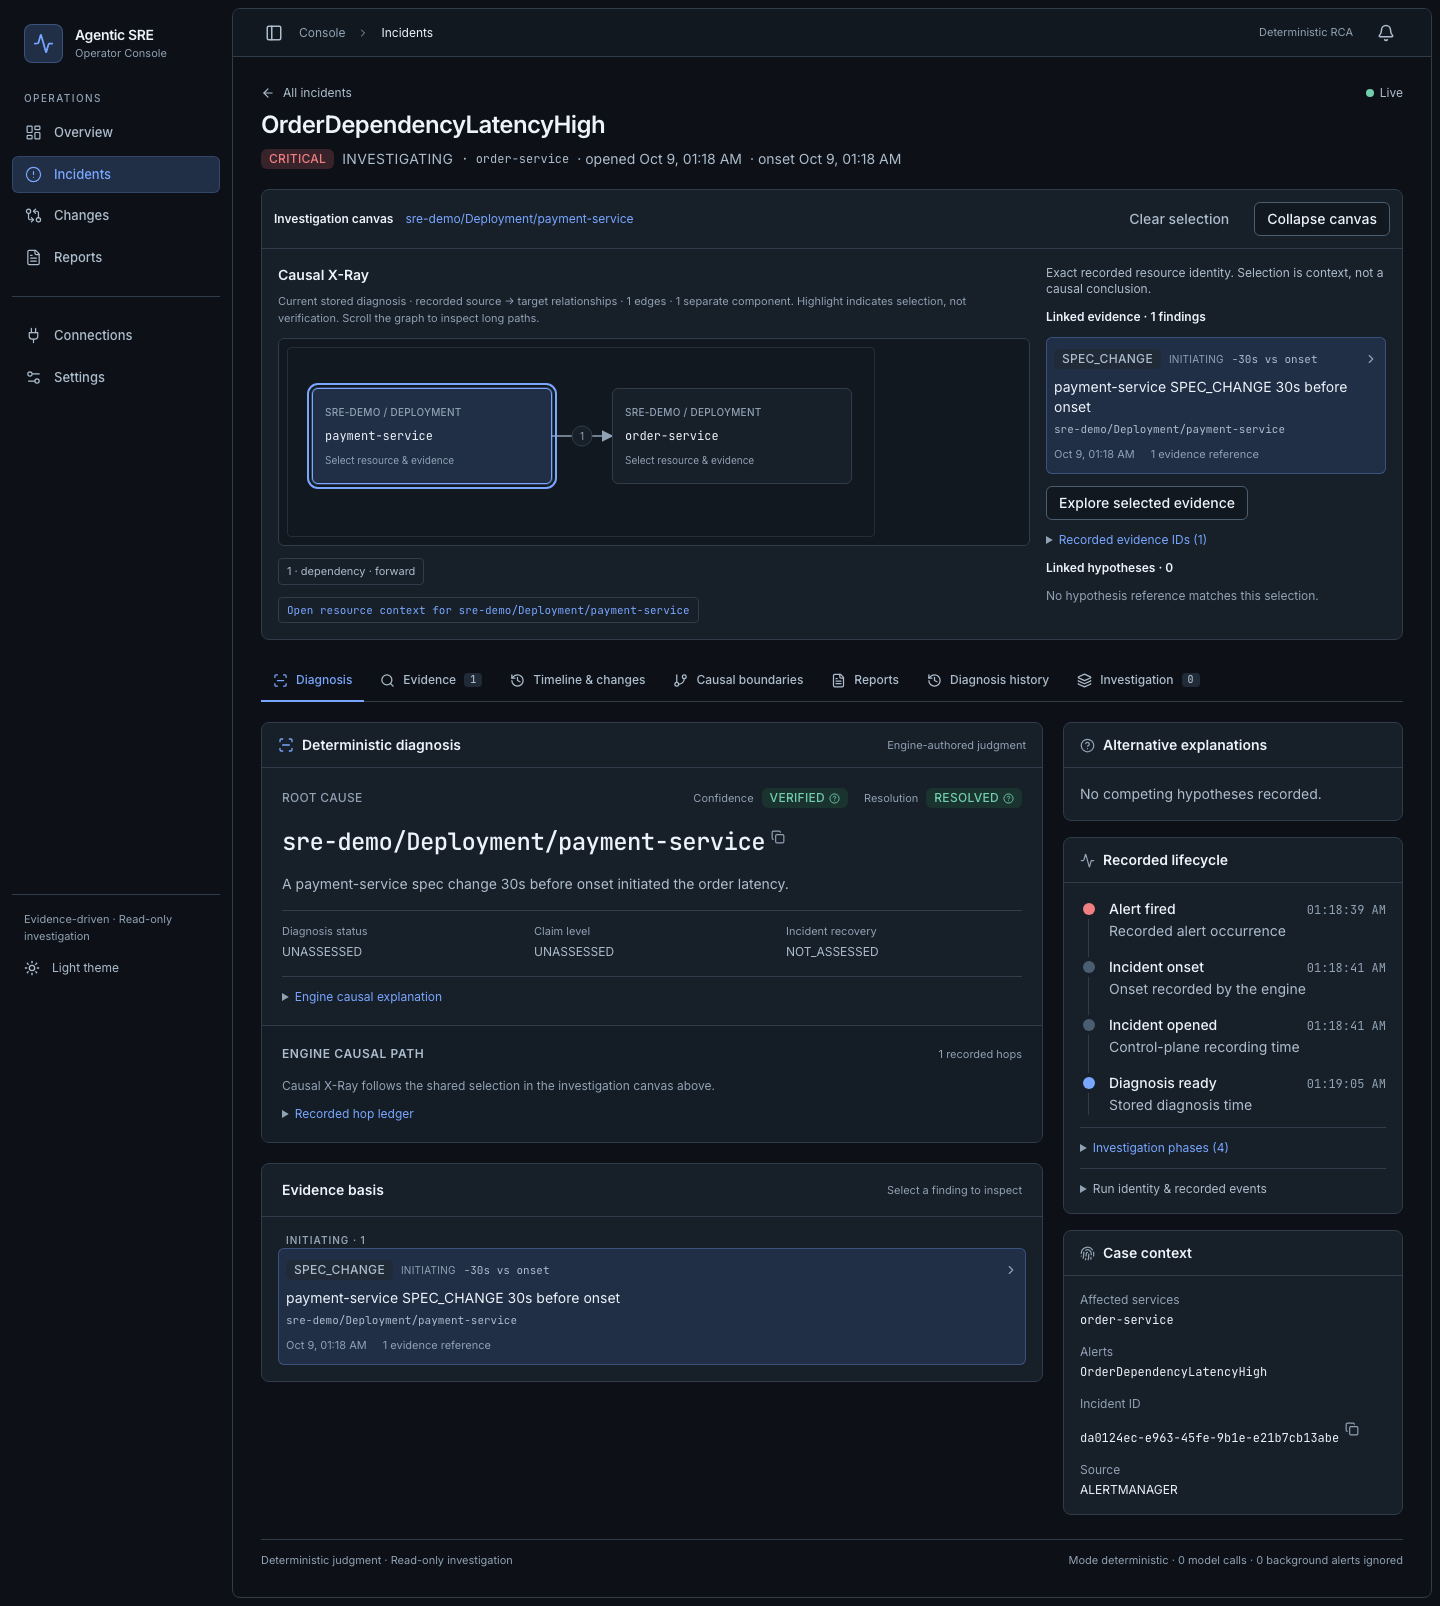
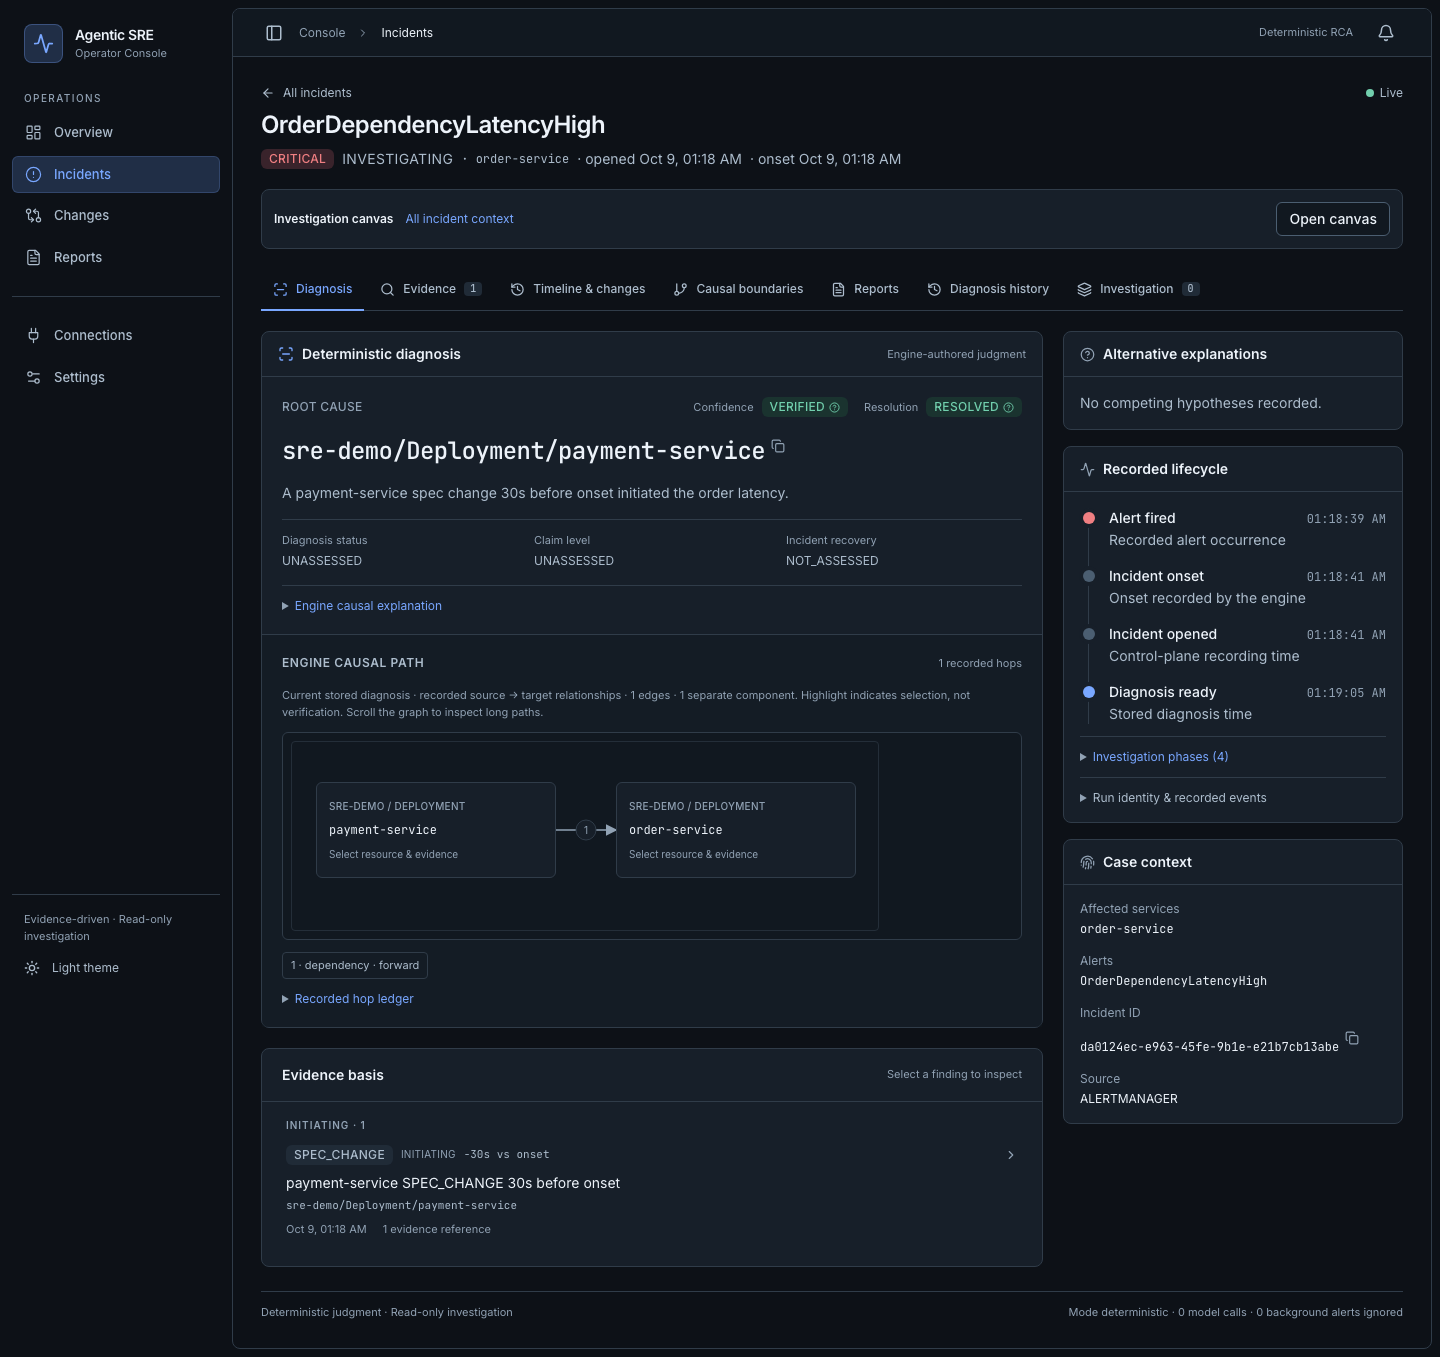
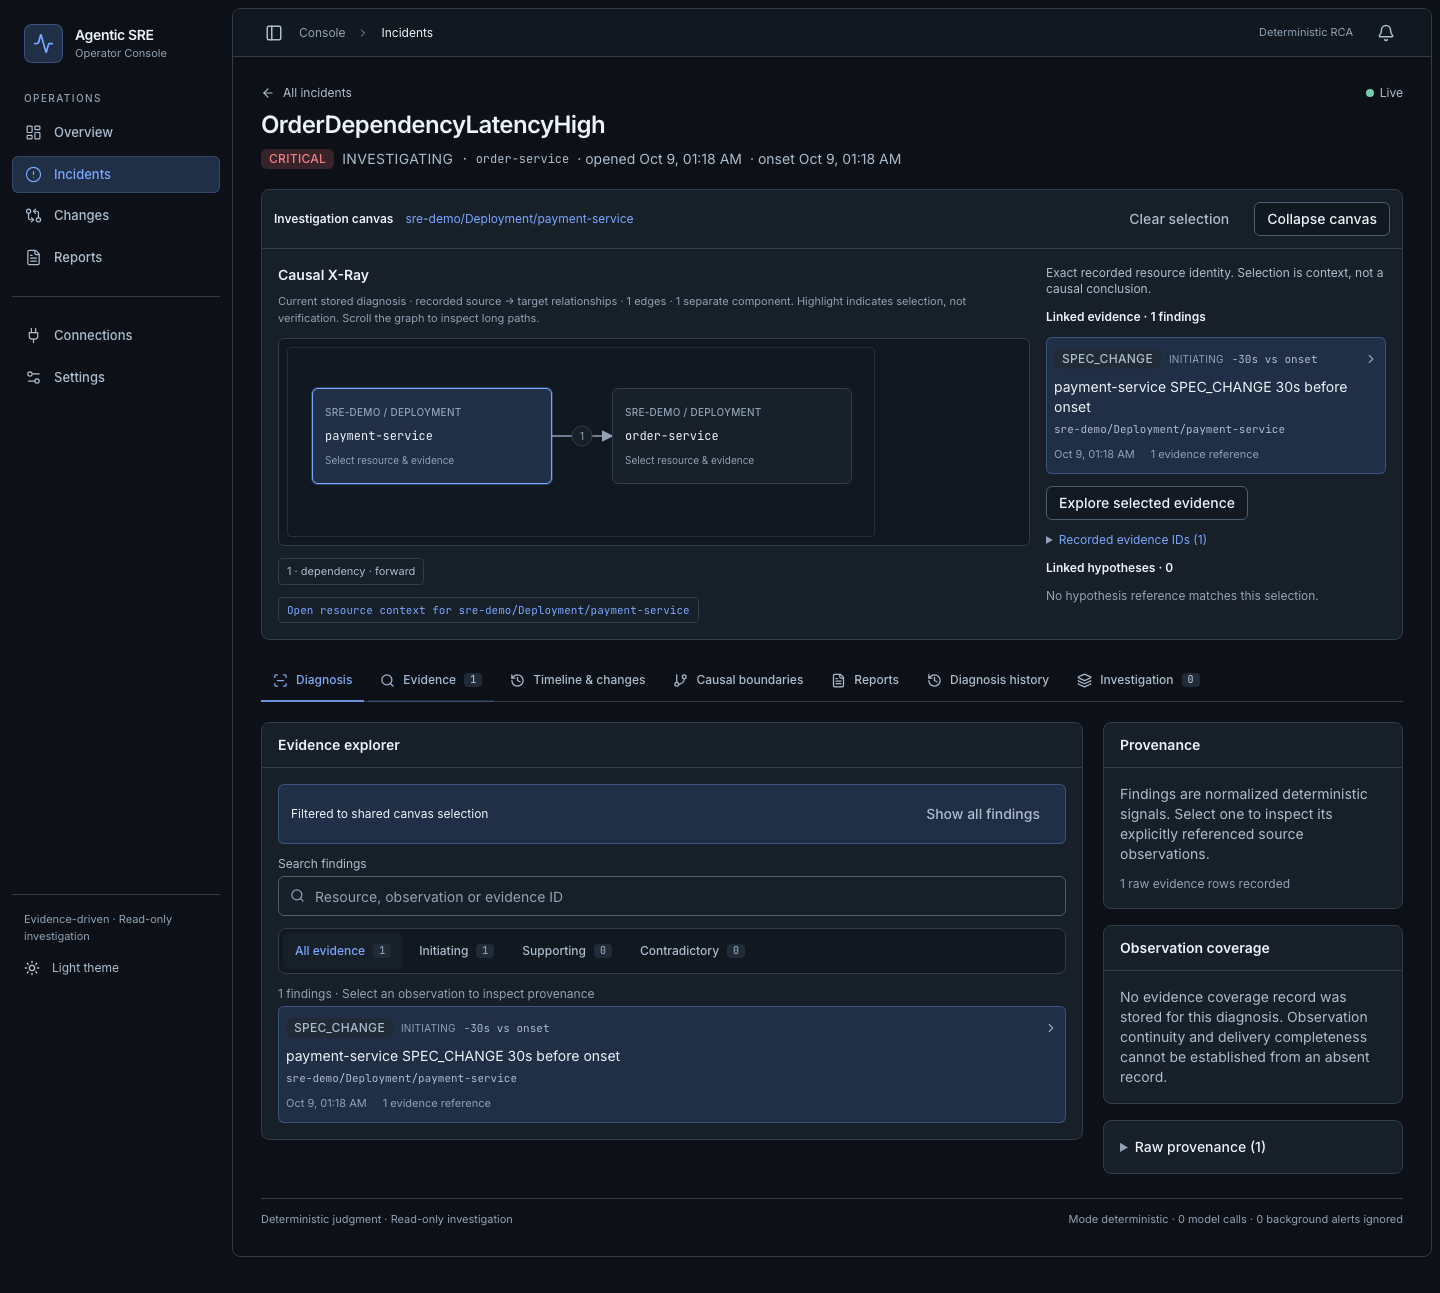
The images below are captures of the production frontend build on repository-provided seeded data. Open any image at full resolution.
Incident workspace
The diagnosis and its evidence basis stay beside investigation context.
Evidence explorer
A resource, Finding or causal-node selection scopes related evidence across views.
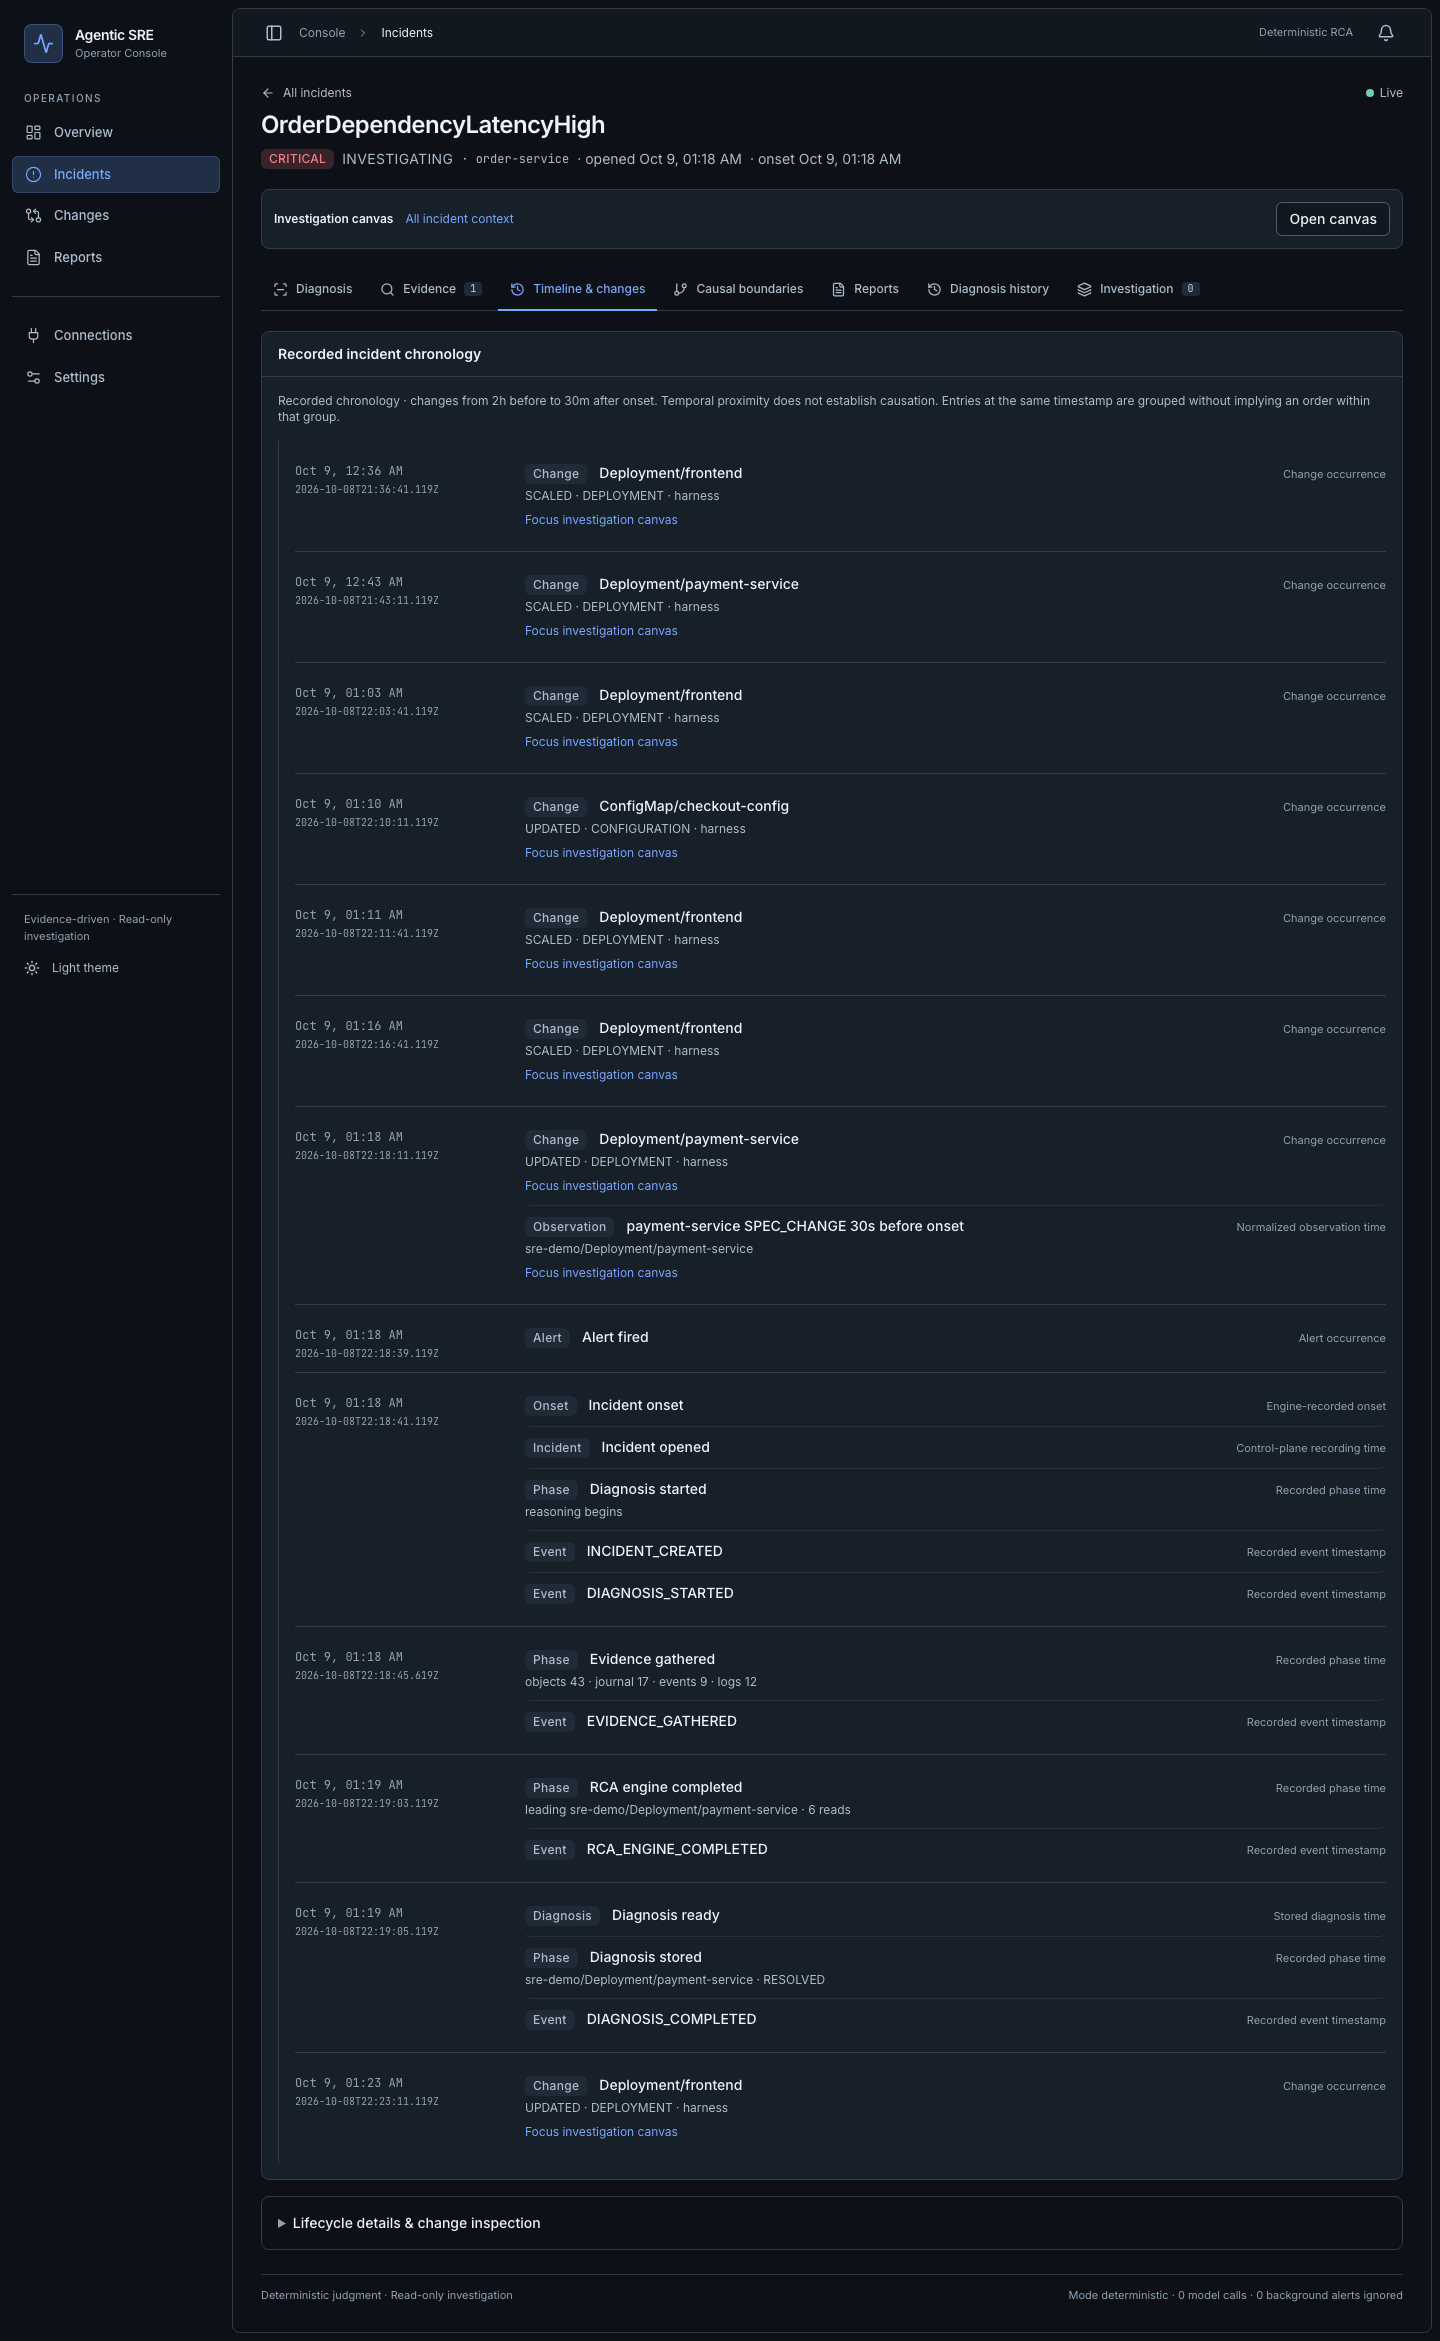
Incident timeline
Occurrence and recording times expose delayed observations instead of flattening chronology.
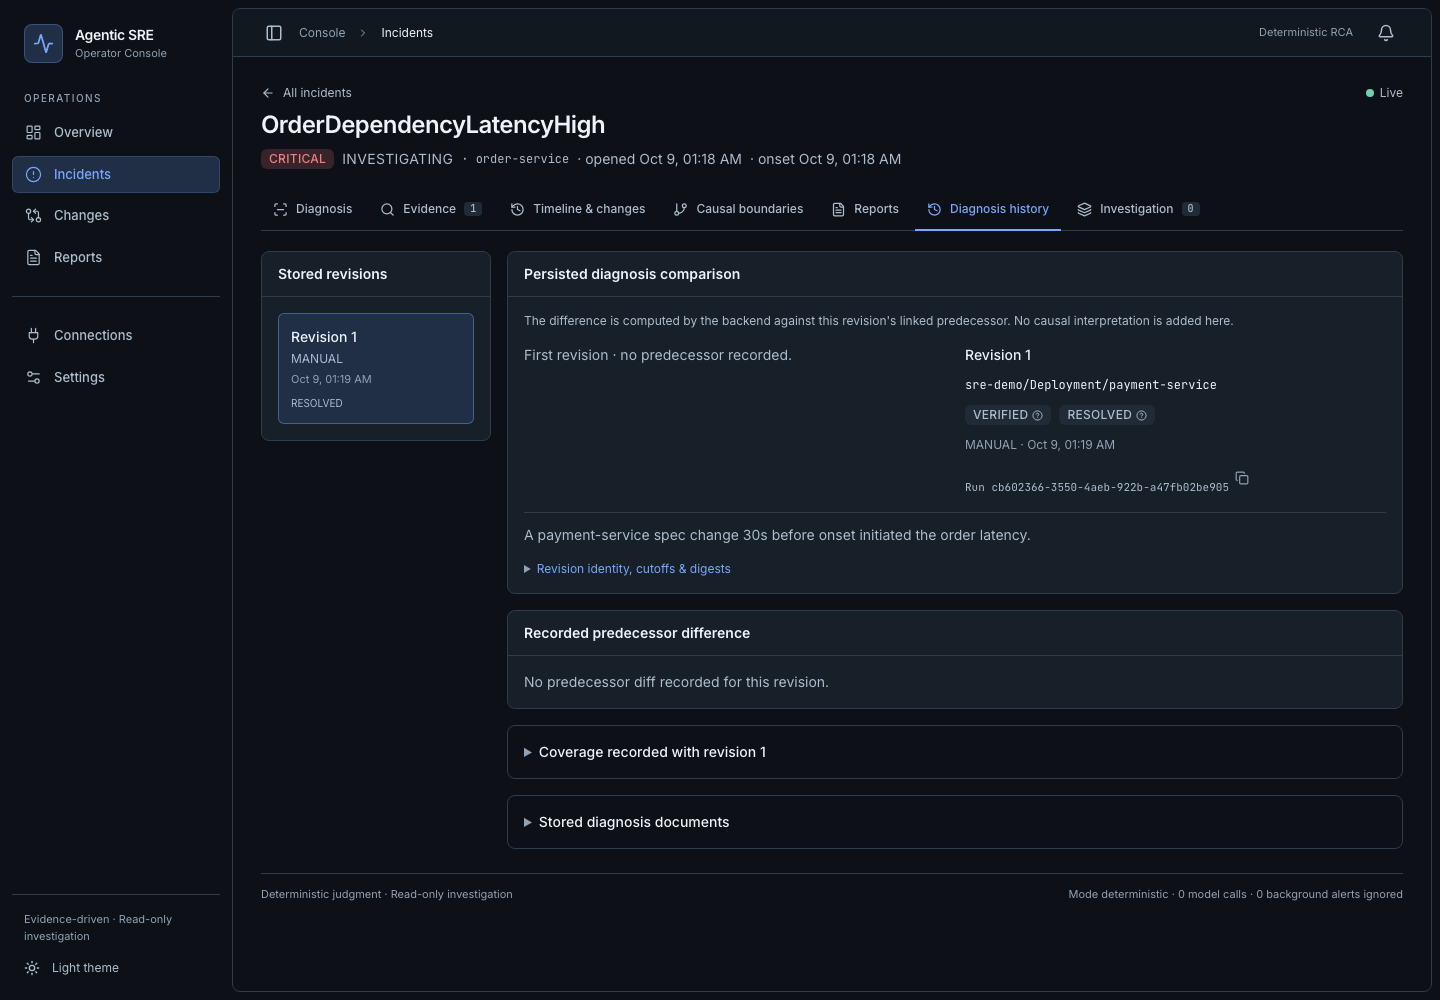
Diagnosis history
Every revision is kept with its metadata, so a diagnosis can be compared with what came before it.
The engineering progressed from ranking candidate roots to checking the evidence semantics of each claim: identity, temporal membership, execution, effect, propagation and the boundaries of what could have been observed.
Resource identity and time are part of the claim
A recreated Pod can reuse a name without being the same instance. UID-aware identity and lifecycle evidence bind faults and resource-pressure effects to the Pod that existed during execution. Evidence membership follows Connector observation time at the cutoff, so late delivery does not become hindsight.
Execution needs an effect
A chaos object being Applied or Spawned is insufficient. Strong authority requires an execution witness at the exact target and an incident effect. Attributed service traces can connect a payment fault to upstream symptoms; an experiment that ended 40 minutes before onset must not earn strong authority.
Shared evidence is explained, not counted twice
A target Pod may appear as a rival because it carries the same fault effect as an upstream actor. Shared-evidence rules explain that manifestation only when the evidence and path justify it. RESOLVED also needs every declared symptom covered; a single witnessed Pod cannot explain a Service while another selected Pod remains ready.
The configuration frontier closes when the API write record predates the window and the scope was followed continuously through onset with delivery proven. A gap is never converted into proof of no change.
Dependencies are answered for a specific claim
A dependency question is answered when it lies on every material claim’s recorded path, and a declared dependency the traced caller never used is identified from server.address attributes on outgoing calls. In the development check, order-service did not call Redis while order-worker did, and the answers differed accordingly.
A symptom met elsewhere answers the dependency question
Engine 2.17.0 reads each firing alert’s own counter samples. When the callers’ alert was met by refusals at another peer before any request reached the dependency, the dependency question is answered from that record. On HOLDOUT23 the rule answered 11 dependency questions, each checked against 19 to 32 candidate requests and every stored span of the run, with none answered wrongly.
Engine 2.17.0 implements these rules. A new rule is pre-registered and confirmed on a fresh held-out testbed set before it counts; HOLDOUT23 confirmed the latest one.
Actor correctness, resolution safety, path agreement and ingestion latency have different denominators and protocols, so each is reported on its own.
ITBench-Lite
On narrow screens, scroll the tables horizontally to read scope and sources.
Measurement
Result
Scope and source
ITBench-Lite exact root cause
18/31, 58.1%
Engine 2.17.0, all 35 scenarios on the full-source path, 31 scoreable. The answer must equal the published label exactly. Report
Evidence-backed causal equivalence
20/31, 64.5%
Engine 2.17.0: the answer is a Schedule whose own spawned experiment ran across the incident’s onset. Reported beside the exact score. Report
TEST25, blind when frozen
17/22, 77.3%
Full-source path against published ground truth on the held-out split of the frozen architecture; raw 17/25, three unmatchable labels excluded. Report
All 35, frozen architecture
26/31, 83.9%
DEV10 plus TEST25 against published ground truth; four unmatchable labels excluded. Report
Since 2026-09-28 all 35 scenarios serve as the development regression set, and engine 2.17.0 reproduces engine 2.2.2’s predictions scenario by scenario. Held-out measurement now comes from the instrumented testbed below.
Read budget and confidence calibration
The frozen bounded TEST25 path used six validated reads per incident: 150 total, with zero tool errors and zero model calls. The bounded path matched the full-source answer on 21/25 TEST25 scenarios, 10/10 on DEV10 and 31/35 combined.
Full-source calibration against ground truth: VERIFIED 13/16 and LIKELY 13/19 (TEST25: 8/10 and 9/15).
A single-node Kind cluster with Chaos Mesh and instrumented service traffic supplies six fault families. The injector and a separate oracle record creation, execution, target effect, propagation, symptom, alert and recovery. The engine never sees the harness’s ground truth. Self-contradictory runs are INVALID and never scored.
Variant A is development data; different injections in held-out variants run with the engine commit, version and manifest hashes frozen. Each run gets a fresh control-plane database, Connector restart and target Pod. Acceptance is fixed in advance: at least 90% valid runs, zero false RESOLVED, zero false strong authority and the isolated decoy never named.
HOLDOUT23, 2026-10-13, engine 2.17.0
27/27 valid runs. The true cause and instance named in every run. Zero false RESOLVED, zero false strong authority, zero false elimination, and the decoy never named. Every pre-registered criterion holds.
Fault family
Held-out injection
Cause named
Dependency fault
Packet loss on payment-service
3/3
Dependency fault (new)
Delay on the Kafka Pod alone
3/3
Direct pod fault
CPU stress on payment-service
3/3
Scheduled recurring fault
Schedule spawning CPU stress
3/3
Configuration rollout
Image change to a missing tag
3/3
Configuration rollout
Environment error rollout (variant C)
3/3
Negative control
Real change plus a CPU-stress decoy
3/3
Negative control
DB-delay rollout plus decoy (variant C)
3/3
Competing causes
Packet loss plus an independent pod kill
3/3
Nine variants with three fresh seeds each; the Kafka delay is new to this set. An execution witness was recorded in 24/27 runs, and the new dependency rule answered 11 questions with none answered wrongly.
25/25 expected outcomes across 19 DEV and 6 HOLDOUT scenarios in the frozen live-suite protocol. It stages faults on a running cluster and grades stored diagnoses: 16/16 actor identifications and 9/9 abstentions were correct, with zero fabricated RESOLVED. The resolution distribution was 0 RESOLVED, 14 AMBIGUOUS and 11 INSUFFICIENT_EVIDENCE; the deterministic paths made zero model calls.
The 2026-09-24 re-anchor and the M16 rerun both document this result.
More telemetry can reveal a competing cause or an uncovered symptom. A trustworthy investigation has to preserve that uncertainty instead of turning every ranking into a verdict. Causal attribution needs evidence of execution and effect; operational correctness needs the ability to reproduce the investigation.
The testbed matters as much as the engine. Fault isolation, independent witnesses, frozen protocols and honest denominators determine what a result actually proves. The outcome is an evidence-driven Kubernetes investigation platform with a deployable Connector, deterministic judgment, replayable evidence and an inspectable console.
In short
What is Agentic SRE?
Agentic SRE is an evidence-driven Kubernetes incident investigation platform. An independently deployable in-cluster Connector holds customer credentials and dials out over gRPC/mTLS. The control plane journals observations in PostgreSQL, a bounded investigator gathers evidence, and deterministic rules verify causal hypotheses. Immutable diagnosis inputs support offline replay, while a React/TypeScript operator console connects causal paths, evidence, timeline and revision history. An optional LLM may select legal reads; it never owns the causal judgment.
What problem does Agentic SRE solve?
An incident root-cause tool becomes a trust problem the moment it can act on a cluster, hold its credentials or hand an operator an unverified answer. A plausible model guess is not a diagnosis, and a ranking's first place is not a cause. Agentic SRE keeps evidence acquisition and judgment separate, keeps credentials inside the customer cluster, records what each diagnosis could not see, and reports ambiguity as ambiguity — then measures correctness, abstention and safety as separate evidence against published ground truth, staged live faults and a testbed whose truth is recorded.